AIVISION Launches Speech-to-Text E1.0: Vietnamese ASR on One GPU
28/09/2026
AIVISION announces Speech-to-Text E1.0 (build aivision-s2s-ev-E1.0.0), a 1.5-billion parameter Vietnamese speech recognition model. It handles code-switching where Vietnamese speakers insert English mid-sentence, and is compact enough to run on a single GPU or directly on-device.
Try it out and integrate the API at s2s.aivgroups.com.
Key Metrics
| Metric | Value | Notes |
|---|---|---|
| Average WER | 11.84% | Across 4 held-out test sets. Lower is better. |
| Vietnamese Read Speech | 4.58% | FLEURS-vi |
| Mixed Vietnamese + English | 15.68% | ViMedCSS (medical), preserves English terminology |
The 1.5B parameter model was trained on over 50,000 hours of Vietnamese audio, including read speech, broadcasting, and natural conversation.
Accuracy by Test Set
WER (Word Error Rate) compared against human transcriptions, across four Vietnamese test sets. Lower is better.
| Test Set | Data Type | WER% |
|---|---|---|
| FLEURS-vi | Vietnamese Read Speech | 4.58 |
| VIVOS | Vietnamese Read Speech | 6.83 |
| ViMedCSS test | Medical, Mixed Vietnamese + English | 15.68 |
| AIV meetings | Real meetings, natural speech, far-field | 20.29 |
| Average | 11.84 |
The AIV meetings set is the most challenging as it features real conversations with overlapping speakers and far-field recording. This is also the most common audio type enterprises encounter when transcribing meetings.
Comparison with Other Open-Source Models
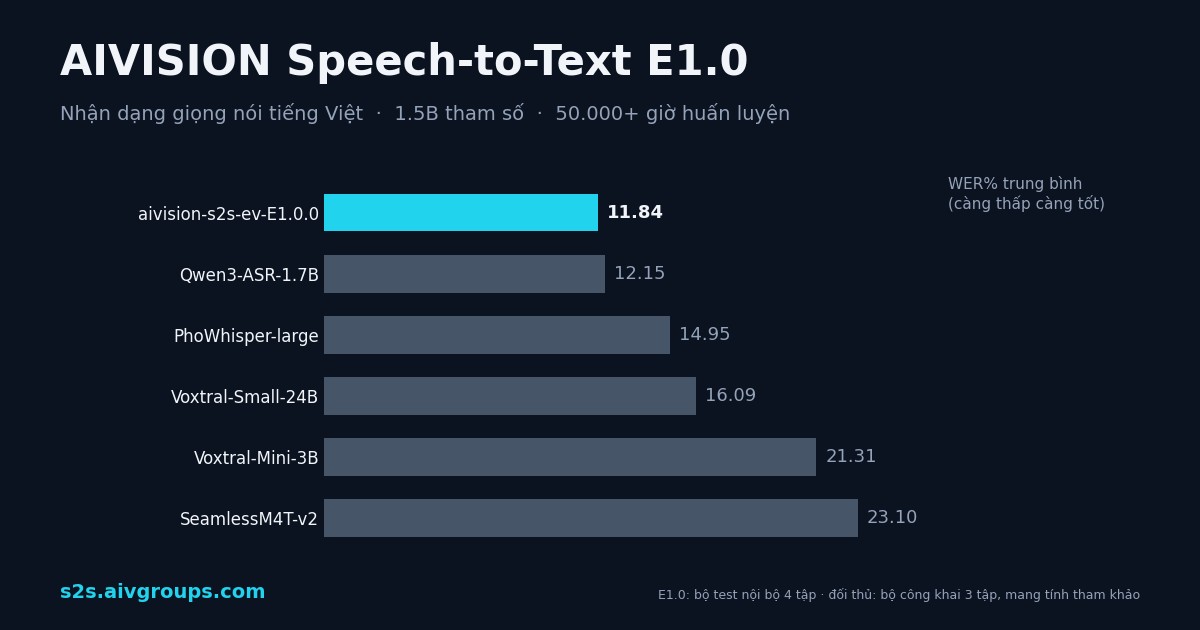
We conducted an independent benchmark on three public Vietnamese test sets (FLEURS-vi, VIVOS, ViMedCSS), 300 sentences per set, on August 29, 2026.
| # | Model | Parameters | Avg WER% |
|---|---|---|---|
| 1 | aivision-s2s-ev-E1.0.0 | 1.5B | 11.84* |
| 2 | Qwen3-ASR-1.7B | 1.7B | 12.15 |
| 3 | PhoWhisper-large | 1.5B | 14.95 |
| 4 | Voxtral-Small-24B | 24B | 16.09 |
| 5 | Voxtral-Mini-3B | 3B | 21.31 |
| 6 | SeamlessM4T-v2 | 2.3B | 23.10 |
PhoWhisper-large performs best on pure Vietnamese read speech (VIVOS 4.79) but is weakest when speakers insert English.
* Comparison Note: Other models' scores were measured on the three public sets. E1.0's 11.84 score was measured on a four-set internal suite, which is harder due to the inclusion of AIV meeting audio. Therefore, the ranking is for reference only and not a strict comparison on the same test set.
Why Choose E1.0
- Vietnamese close to human transcription. Clean read speech achieves 4.58 WER on FLEURS-vi and 6.83 on VIVOS, matching the best open models despite being much smaller.
- English within Vietnamese sentences. Preserves English technical terms instead of mis-transliterating them: 15.68 WER on the mixed-language medical set, where Vietnamese-only models typically fail most.
- Small enough for self-hosting. The 1.5B parameter model runs on a single GPU or on-device, keeping audio data within your system, eliminating the need for massive servers and per-minute cloud fees.
Evaluation Methodology
- Fixed 16 kHz audio, compared against human transcriptions.
- Numbers are normalized to text on both sides; WER is calculated identically across all test sets.
- English accuracy is currently reported as English embedded in Vietnamese. We have not yet published WER for pure English.
Try It Out
Visit s2s.aivgroups.com to try the model and view API documentation. For enterprise on-premises deployment consulting, please contact the AIVISION team.